Make AI Hear What Matters: Accents, Code-Switching, Duplex & Context — The Next Leap in Speech Training Data
New Open-Source Release | Chuan-Yu 12-City Sub-Dialect Speech Dataset: Helping Large Models Understand the Living Voices of Sichuan and Chongqing

Magic Data Open-Sources Five Dialect TTS Datasets: Native Speakers Aged 30–60 Bring Authentic Chinese Regional Voices to Life
Day 1 Highlights from ICASSP 2026

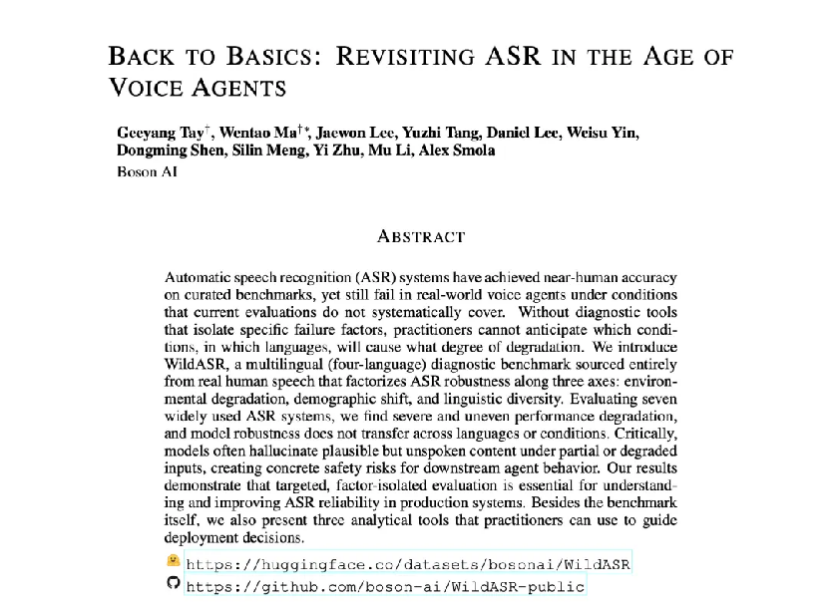
What ASR Still Gets Wrong: A Closer Look at Real-World Failures
Global Data for Voice Agent Meetup Launches | Debut in Singapore

Developing Emotionally Intelligent AI: Magic Data Releases a Multi-Speaker Emotional Speech Dataset

Breaking the TTS Naturalness Bottleneck: Full-Duplex Conversational Datasets Make Synthetic Speech Sound More Human

From Passive Command Execution to Proactive Needs Anticipation: Building Emotionally Intelligent, Spontaneous Human-Machine Interactions with Magic Data’s High-Quality Conversational Datasets
从机械指令执行到智能默契伙伴:Magic Data高质量语音数据集将助力构建情感智能AI
