The next milestone for Voice AI isn't just "understanding a sentence"—it's "catching the flow of a conversation."
In authentic human communication, hesitations, pauses, backchannels, interruptions, and overlapping speech happen constantly. Beyond understanding what is being said, a Voice Agent must judge when to respond, when to listen, and how to participate naturally in a dialogue.
Mastering these capabilities requires real-world, full-duplex dialogue data.
Over the past year, MagicHub.com has successively open-sourced natural full-duplex dialogue datasets in Chinese, English, and Japanese, which have been widely adopted by conversational model developers and open-source speech framework teams for research and benchmarking. Notably, Boson AI co-founders Mu Li, Alex Smola, and their research team selected MagicHub’s duplex dialogue data as a core corpus for the WildASR benchmark.
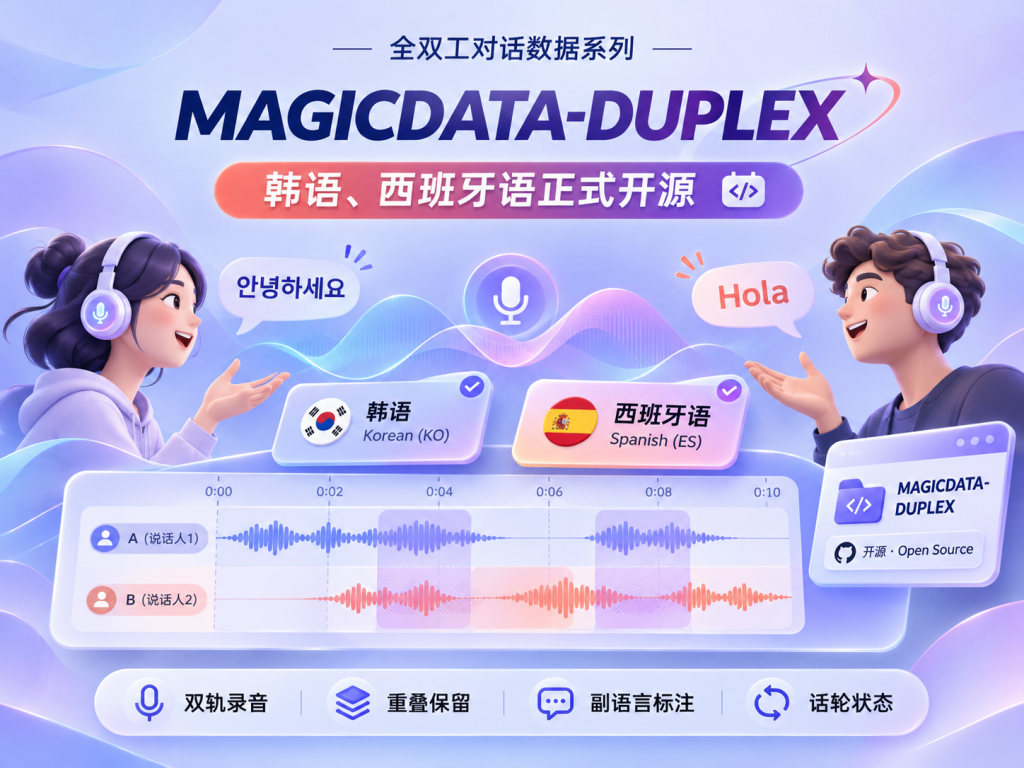
Today, the MAGICDATA-DUPLEX full-duplex dialogue series expands once again—Korean and Spanish are now officially open-sourced!
From Chinese, English, and Japanese to Korean and Spanish, we are continuously broadening our coverage of multilingual, real-world conversational data to empower research in real-time voice interaction and Voice AI.
Two New Languages Officially Open-Sourced
Every language carries its own expressive habits and conversational rhythms. These newly released Korean and Spanish datasets bring a wider variety of authentic conversational samples to multilingual full-duplex speech research.
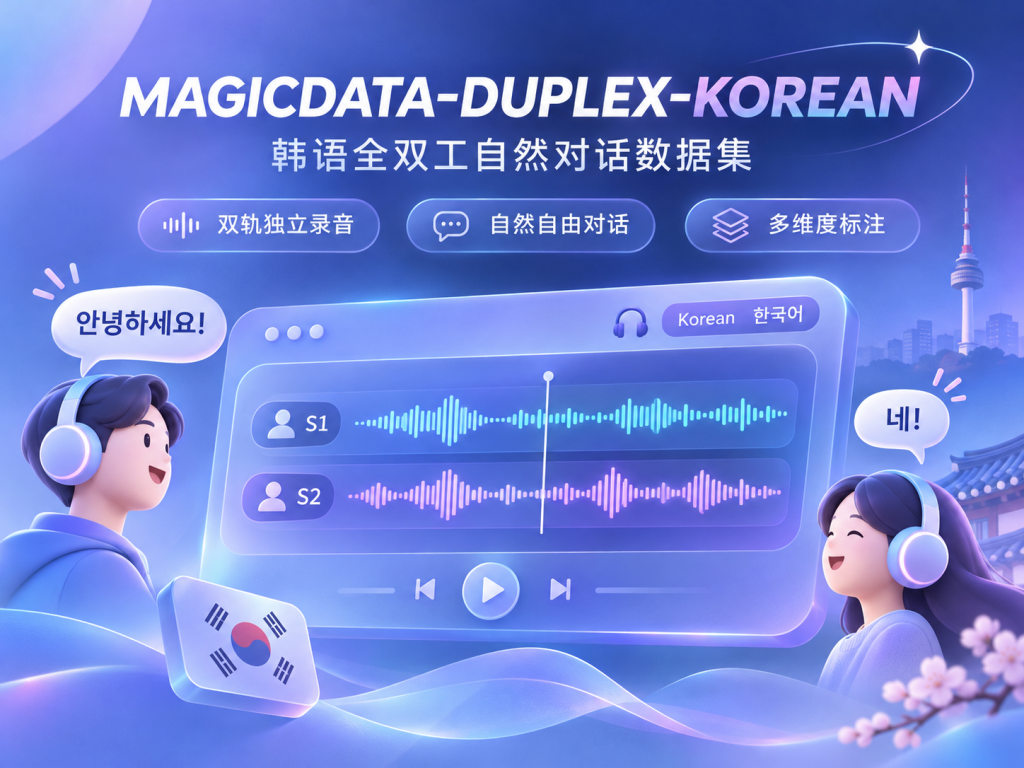
Korean: Understanding Both Context and Conversational Rhythm
In natural Korean conversation, the hardest part isn't recognizing words—it's recognizing relationships and rhythm. Honorifics, sentence-final intonation, instant backchannels, and turn-taking all shape the pace and dynamics of communication:
- Honorifics and register shifts: Different honorific forms and speech styles reflect the social relationship, familiarity, and conversational context between speakers.
- Attitude conveyed through sentence-final intonation: Even a simple phrase like "알겠어요" (algesseoyo, "I understand") can signal genuine agreement, perfunctory compliance, or impatience depending on its intonation.
- Backchannels and polite expressions: Brief responses like "음" (eum), "아하" (aha), "네" (ne), and "그렇네요" (geureoneyo) combine with context and politeness cues to convey active listening, comprehension, or agreement.
- Natural turn-taking and overlapping speech: Backchannels, latching, interruptions, and pauses frequently interweave in real conversations, creating intricate interactive rhythms.
For full-duplex models, the challenge in Korean goes beyond understanding what was said—it requires judging when and how to respond.
This open-source release preserves natural conversational phenomena such as backchannels, pauses, interruptions, and overlapping speech, supporting research in Korean turn-taking control, backchannel recognition, interruption detection, and real-time voice interaction.
👉 Download the Dataset: https://magichub.com/datasets/mdt-duplex-korean-training-dataset/
Spanish: Decoding Real Interaction Through Overlaps and Rapid Latching
Spanish is one of the most widely spoken languages globally and stands right behind English as a top priority for multilingual voice interaction scenarios.
In natural Spanish conversations, instant feedback, rapid latching, dynamic intonation shifts, and vocal overlaps provide rich samples for full-duplex speech research. Its conversational style is remarkably distinct:
- Overlap-tolerant interaction: Two people speaking simultaneously isn't perceived as an "interruption"—it signals "I'm actively listening."
- Zero-gap latching: Short feedback cues like sí, claro, ajá, and ya appear at high frequencies, often embedded right in the middle of the other speaker's sentence.
- Wide pitch and intonation jumps: Emotion, emphasis, and questions shift rapidly through stress and pitch variations.
- Collaborative turn completion: Friends frequently chime in to finish each other's half-spoken sentences.
- Significant regional variation: Peninsular Spanish and Latin American Spanish differ noticeably in pronunciation, intonation, and speech rhythm, with distinct characteristics across different countries and regions in Latin America.
For full-duplex models, the key is no longer simply "waiting for silence before answering," but understanding diverse interactive behaviors and responding naturally within a continuous dialogue stream.
This dataset supports research in Spanish turn-taking, overlapping speech analysis, interruption detection, natural latching modeling, and multilingual real-time voice interaction.
👉 Download the Dataset: https://magichub.com/datasets/mdt-duplex-spanish-training-dataset/
MAGICDATA-DUPLEX: Teaching Models Authentic Human Conversation
MAGICDATA-DUPLEX is a continuous open-source series of multilingual, full-duplex natural dialogue datasets launched by MagicHub.com, focusing on preserving dynamic interactive behaviors such as interruptions, overlaps, backchannels, and pauses in real-world communication.
The newly added Korean and Spanish datasets adhere to the series' unified standards and feature:
- Dual-channel independent recording: Each speaker is recorded on a separate channel, natively preserving overlapping speech without requiring post-hoc source separation.
- Authentic, unscripted dialogue: Non-read and non-scripted conversations that capture spontaneous responses, follow-up questions, interruptions, and latching.
- Multi-dimensional fine-grained annotations: Includes timestamps, speaker IDs, text transcriptions, paralinguistic cues (laughter, sighs, hesitations, etc.), and turn-taking states (yield/take turn, wait, interrupted).
- Standardized audio format: 16kHz / 16-bit WAV, with ~10 hours of natural dialogue data open-sourced each for Korean and Spanish.
- Open-source for research: Released under the MagicHub Open-Source License for non-commercial research use.
MAGICDATA-DUPLEX now covers five languages:Chinese · English · Japanese · Korean · Spanish
Our goal is to build more than just a multilingual speech transcription corpus—we aim to provide a data foundation that teaches models how humans listen, respond, interrupt, and converse naturally.
Looking ahead, MAGICDATA-DUPLEX will continue expanding to more languages to advance research and real-world applications in full-duplex voice interaction.
See You in Sydney This December! Full-Duplex Voice AI Meetup Coming Soon
Beyond open-sourcing data, we look forward to connecting face-to-face with researchers and developers.
This December, alongside NeurIPS 2026 in Sydney, MagicHub will host the Full-Duplex Voice AI Meetup!
We plan to bring together full-duplex speech researchers, open-source framework creators, and developers for in-depth discussions on real-time voice interaction:
- Open-Source Framework Deep Dives: Creators of open-source full-duplex frameworks, including Sophon-Realtime, will share their technical explorations and hands-on experience.
- Data Methodology Sharing: The Magic Data team will present best practices in full-duplex data annotation and multilingual dataset construction.
- Frontier Technical Discussions: Focusing on core challenges such as turn-taking control, interruption detection, paralinguistic modeling, and cross-lingual transfer.
- Live Demos & Developer Networking: Showcasing real-time voice interaction implementations and fostering collaboration across the open-source community.
From real-world conversational data to open-source frameworks, and from academic research to practical deployment, we hope to gather fellow innovators passionate about Full-Duplex Voice AI to exchange ideas and share insights.
Event dates, venue, guest speakers, and registration details will be announced soon—stay tuned!
See you in Sydney this December!
Access the Open-Source Datasets:
- Korean: https://magichub.com/datasets/mdt-duplex-korean-training-dataset/
- Spanish: https://magichub.com/datasets/mdt-duplex-spanish-training-dataset/
MagicHub Open-Source Community: https://magichub.com
Commercial Licensing Inquiries: business@magicdatatech.com
