
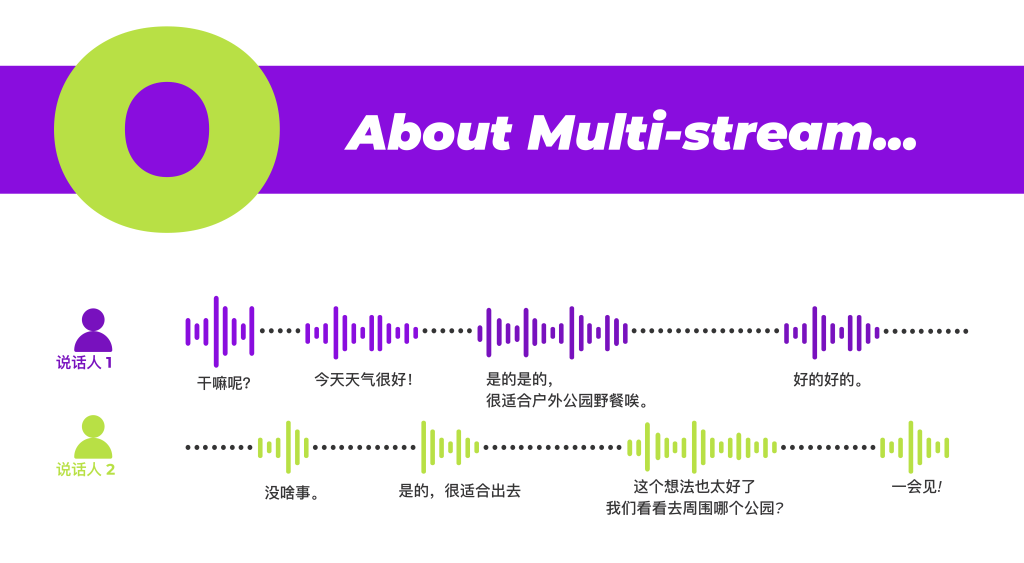
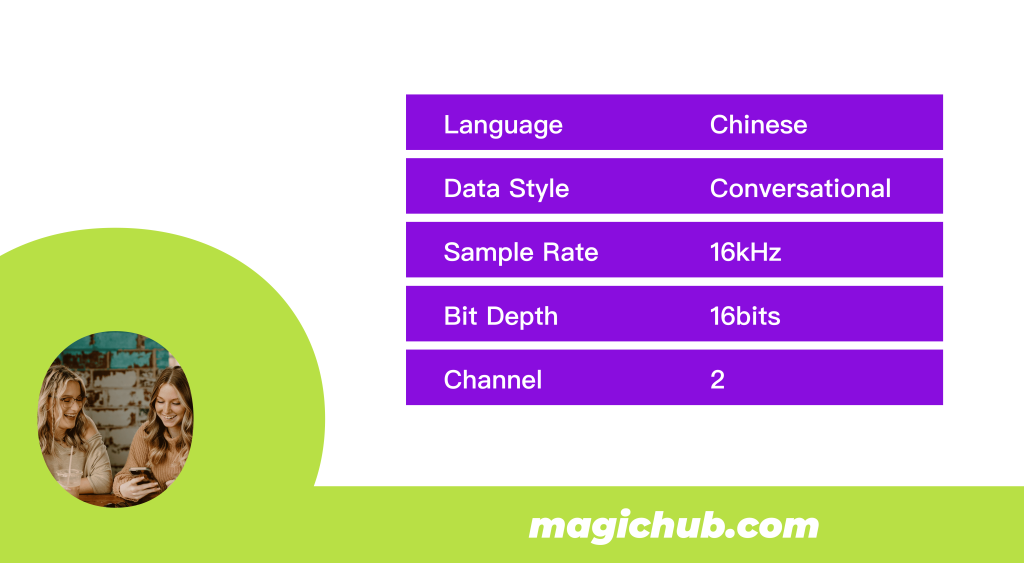
The Multi-stream conversation dataset developed by MagicData captures each speaker's audio track and labels each speaker separately, thereby preserving the natural occurrences of interruptions, interactions, and other dynamics in conversation. By isolating each speaker's audio, we can provide clearer and more accurate training data, enabling models to more effectively understand and respond to natural conversational exchanges. To facilitate broader understanding and accessibility, we have released a 10-hour sample as part of our open-source initiative: "Multi-stream Spontaneous Conversation Training Datasets_Chinese".
This dataset is part of the MAGICDATA-DUPLEX series, a collection of multilingual full-duplex conversational speech datasets designed to support research and development in natural voice AI interaction. It is also known as MAGICDATA-DUPLEX-CHINESE, following the unified naming convention of the series.
The dataset focuses on authentic Chinese conversations, preserving natural turn-taking, interruptions, overlapping speech, and other interactive features essential for full-duplex speech model training and evaluation.
For more commercial datasets, please contact business@magicdatatech.com.
